One serving start with cooperative MoE on. The on/off comparison has not run; no cooperative MoE speedup is claimed.
One OpenAI-compatible endpoint across all three. The recipe is pinned so you can rebuild it, with public benchmarks and the misses left in.
Three DGX Sparks · one endpointRank 0 serves the API; all three run inference.
Release
v1.8.4
Weights
Stock GLM-5.3 Flash · abliteration is opt-in
Hardware
Three DGX Sparks · RoCE · one endpoint
Measured on our three Sparks.
v1.8.4 with stock weights, one serving start. Code: five repeats per stream count. Prose and structured: two sweeps. Prefill: eight turns. Ranges describe variation within this start, not confidence intervals.
Decode is aggregate tok/s across requests started together, each forced to 512 output tokens. Code uses temperature 0. Prefill is tok/s per Pi turn over eight turns, measured after page-cache hygiene.
Prefill · one stream
1,197.1– to 1,273.4 tok/s
No v1.1 run on this benchmark.
Code decode by concurrent streams · tok/s, all streams combined
v1.8.4
Range across repeats
one stream · median 72.9 tok/s
v1.8.465.2– to 84.7
2 streams · median 105.4 tok/s
v1.8.4103.0– to 106.4
4 streams · median 136.4 tok/s
v1.8.4136.2– to 139.5
8 streams · median 174.7 tok/s
v1.8.4164.2– to 180.9
0200 tok/s
Results by workload
Code medians accompany the full repeat ranges. Prose and structured show their two-sweep ranges. Every decode rate is the aggregate across all concurrent streams.
Decode · tok/s · 512 forced output tokens per stream
Workload
Streams
Range, tok/s
Median, tok/s
Repeats
Code
one stream
65.2– to 84.7
72.9
5
Code
2 streams
103.0– to 106.4
105.4
5
Code
4 streams
136.2– to 139.5
136.4
5
Code
8 streams
164.2– to 180.9
174.7
5
Prose
one stream
44.7– to 46.1
Not reported
2
Prose
2 streams
63.7– to 65.5
Not reported
2
Prose
4 streams
86.0– to 88.4
Not reported
2
Prose
8 streams
105.6– to 106.4
Not reported
2
Structured
8 streams
202.7– to 220.9
Not reported
2
Code at two streams: 103.0 to 106.4 tok/s over five runs, overlapping v1.8.0's 101.0 to 103.9.
v1.8.0 results, preserved as published
Decode is the aggregate rate of 1, 2, 4 or 8 code-writing requests started together (this build serves the Pi coding agent), each forced to 512 output tokens at temperature 0 with thinking off and no prefix-cache reuse, counted from the first to the last streamed token; prefill is the range over eight Pi-shaped coding-agent turns, each extending a cached prefix, measured right after a page-cache hygiene step.
Prose decode: 44.3– to 49.1 tok/s at one stream; 83.3– to 90.7 tok/s at four streams. One serving start, two sweeps.
Serving starts published with v1.8.0
Each row is one start of the server, labelled by build. Decode ranges span its sweeps; prefill spans individual turns. Every start we measured is listed.
All figures in tok/s. Decode above one stream is the aggregate across all streams.
Serving start
Prefill
Decode c1
Decode c2
Decode c4
Decode c8
Stock weights (default)
v1.8 · stock weights · one serving start, two sweepsv1.8.0, frozen release
1,195.0– to 1,262.6
68.2– to 73.3
101.0– to 103.9
136.9– to 141.7
174.0– to 179.7
v1.7.4 · stock weights · one serving start, two sweepsv1.7.4 base recipe, stock weights, QA profile
1,196.7– to 1,263.3
73.0– to 75.7
104.1– to 112.5
137.8– to 141.5
180.1– to 181.0
Edited weights (opt-in)
v1.7.4 · edited weights, opt-in · one serving start, two sweepsv1.7.4 base recipe, no decode levers
1,185.6– to 1,266.2
62.7– to 64.4
106.5– to 108.0
126.8– to 136.5
168.3– to 172.5
Edited-weight rows are measured as they are and never scaled to stand in for stock weights.
Their run used JSPARK3 v1.1 with one added patch. It was not a run of v1.8.4.
Our three DGX Sparksruns v1.8.4Their three GB10 machinesran v1.1 with one added patch
We tried DeepSeek, measured it, and came back.
Tempo was my DeepSeek experiment, and I measured it seriously. Its tok/s held up, but it overthinks, and time to finish a task is what I actually feel. GLM-5.3 Flash is better at agent and coding work, and better in almost every other way I use it, so the numbered line runs GLM again.
You need three DGX Sparks, fast direct connections between them (RoCE), and enough disk space. The install guide checks your machines before anything starts.
The first requests after a fresh install can be about 1 s slower once, while GPU kernels compile.
The default install uses Brandon M. Music's EXL3/TR3 4-bpw checkpoint of Z.AI's GLM-5.3 Flash, downloaded from Mia-AiLab's byte-identical re-host. JSPARK3 provides a mirror. Stock means unedited quantized weights. Abliteration is an explicit opt-in.
Choose stock or edited behavior before launch. Changing modes currently requires a service restart and recomputes conversation prefixes.
Brandon M. Music created the ShapleyMcg EXL3/TR3 4-bpw checkpoint that every rank loads. The recipe downloads Mia-AiLab's byte-identical re-host at 25a44fd, declared byte-identical to Brandon's source revision 5ab363a8. JSpark3 provides a mirror. Thanks to MiaAI-Lab for the EXL3 serving recipe and runtime work used by JSpark3, including prefix caching and the cooperative-MoE kernel adapted for TP3. FlyCockpit for the three-Spark EXL3 recipe. turboderp for ExLlamaV3. coolbho3k and gabewillen for display-reserve KV backing and its GLM adaptation. plotarmordev for fine-grained prefix hits. vcruz305 for the K2 recipe lineage and the K-pool tail correction it inspired. tonyd2wild for scheduler and concurrency benchmarking context. sfxnz for DGX Spark serving context. Inco AI for DFlash2. z-lab for DFlash. Z.AI for GLM-5.3 Flash. The vLLM project for the engine.
JSpark3 did not train, fine-tune, or quantize anything. The contribution is the three-Spark architecture, the runtime adaptation, the operating envelope, the experimental campaign, and the reproducible serving recipe.
Thanks to @unsaltedbutter-ai for the first community run on their own three GB10 machines, shared in PR #9.
This work includes or was produced using ShapleyMcg, created by Brandon M. Music (https://github.com/brandonmmusic-max/shapleymcg). ShapleyMcg is licensed under the ShapleyMcg License v1.0, an attribution-required license that grants no rights to the person known as "0xSero." Use of ShapleyMcg without this attribution is unlicensed.
This release's third-party notices record upstream authors, repositories, revisions, and licenses. The required ShapleyMcg attribution is preserved in the repository and model mirrors.
@misc{music2026shapleymcg,
  author = {Music, Brandon M.},
  title  = {ShapleyMCG: An Auditable Calibration-to-Encoding Pipeline for
            Low-Bit Mixture-of-Experts Models},
  year   = {2026},
  url    = {https://github.com/brandonmmusic-max/shapleymcg},
  note   = {Licensed under the ShapleyMcg License v1.0}
}
From the v1.1 page, kept as published
ArchitectureHow three Sparks become one endpoint+
Each Spark holds one tensor-parallel shard and one third of the routed experts. Cadence adds an INT8 QKV decode shadow and request-local speculative width control to this three-rank foundation.
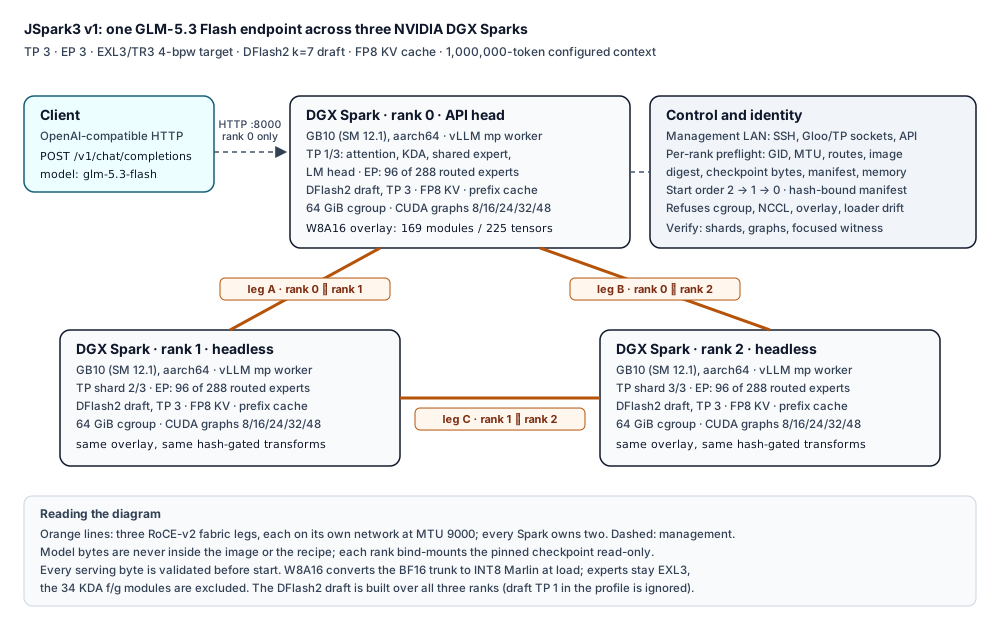
JSpark3 Cadence: one GLM-5.3 Flash endpoint across three NVIDIA DGX Sparks
Orange lines: three RoCE-v2 fabric legs, each on its own network at MTU 9000; every Spark owns two. Solid arrowed line: the HTTP serving path, Rank 0 only. Dashed: management.
In motion: one request. It comes down the HTTP link, Rank 0 takes it, the three ranks exchange on every leg, and the answer goes back up the same link.
Model bytes are never inside the image or the recipe; each rank bind-mounts the pinned checkpoint read-only.
Every serving byte is validated before start. W8A16 converts the BF16 trunk to INT8 Marlin at load; experts stay EXL3, the 34 KDA f/g modules are excluded. The DFlash2 draft is built over all three ranks (draft TP 1 in the profile is ignored).
The base topology shared by both releases. Rank 0 exposes the API; ranks 1 and 2 are headless peers. Open the SVG.
Topology
Tensor parallel 3 and expert parallel 3. Every rank holds a shard of attention, KDA, the shared expert and the LM head, plus 96 of the 288 routed experts. The DFlash2 draft is built over all three ranks; the profile's draft TP 1 setting is ignored by this loader, so the diagram shows what is actually loaded.
Fabric
Three RoCE-v2 legs, each on its own network at MTU 9000. Every Spark owns two fabric interfaces. Preflight checks the GID, MTU and routes on each rank before anything starts.
Overlay
The BF16 trunk is converted to INT8 Marlin at load: 169 modules, 225 tensors, group ladder 128/64/32. The 34 KDA f/g modules are excluded. It frees 1,595,392,320 bytes per rank.
Lifecycle
Start order 2, then 1, then 0, bound to a hash-checked release manifest. The entrypoint refuses on cgroup, NCCL, overlay or loader drift. Verify confirms shards, graphs and a focused witness.
v1.1 benchmarksThe numbers, then the comparisons+
Current Cadence decode, historical prefill, and the configured context. Each has its own scope; the historical comparisons follow.
87.67tok/s
v1.1 structured decode, median of three battery medians. Code 68.77, prose 34.64; descriptive, not paired effects.
223.14tok/s
v1.1 four-stream aggregate, median of all three original-client code waves. Mean per stream: 56.59 tok/s.
1,234tok/s
historical v1.0.0 prefill: one 113,908-token prompt divided by 92.3 s to first token. No comparable v1.1 rerun.
1,000,000tokens
configured context with FP8 KV, not verified maximum capacity. The v1.1 long-context witness confirms the kernel fix, not this limit.
Three Sparks, thinking off, temperature 0. Current decode figures are descriptive, not paired release effects. The repository benchmarks explain estimators, all repeats and limits.
Historical comparisons with other recipes
These v1.0.0 tables retain their original measurements. Each row names its node count.
Historical v1.0.0, on their benchmarks
The authors' pinned scripts, run unchanged against JSpark3 v1.0.0 except for endpoint and model name. Author values are their published results; these tables are historical.
Comparison as measured on 2026-09-02; other projects have released newer versions since.
FlyCockpit's benchmark, the same three Sparks
Decode, tok/s (mean of three runs)
Hello (17-token stop)
1.23xratio
JSpark3 v1.0.03 Sparks46.110
runs 46.106 / 46.405 / 45.820
FlyCockpit TP33 Sparks37.367
runs 37.9 / 36.9 / 37.3
Structured count 1 to 200
1.21xratio
JSpark3 v1.0.03 Sparks84.243
runs 83.988 / 84.580 / 84.161
FlyCockpit TP33 Sparks69.567
runs 69.0 / 68.5 / 71.2
is_prime code
1.18xratio
JSpark3 v1.0.03 Sparks66.543
runs 65.840 / 68.246 / 65.544
FlyCockpit TP33 Sparks56.400
runs 52.3 / 58.7 / 58.2
Draft acceptance 0.8324 against FlyCockpit's 0.815. FlyCockpit's runs were first-serve at GPU memory utilization 0.87; these were warm-server runs at 0.83, the release envelope.
Mia's bench_decode, their two Sparks against our three
Median of five 400-token runs, tok/s
Structured count 1 to 200
1.35xratio
JSpark3 v1.0.03 Sparks88.17
Mia TP22 Sparks65.1
Prose hash-map
1.36xratio
JSpark3 v1.0.03 Sparks36.78
Mia TP22 Sparks27.1
Accepted-per-draft ratios match theirs almost exactly: 0.9533 against 0.959 on structured, 0.3357 against 0.341 on prose. These similar acceptance ratios accompany higher observed decode rates.
Mia's sparkDash decode protocol
Estimator
Mia TP2, 2 Sparks
JSpark3, structured count3 Sparks
JSpark3, clamp code3 Sparks
Concurrency C1
per-stream decode tok/s
62.9
86.56
84.47
time to first token
719 ms
461 ms
391 ms
Concurrency C2
per-stream decode tok/s
51.7
79.26
70.56
aggregate decode tok/s
103.3
76.95
139.77
Concurrency C4
per-stream decode tok/s
37.1
50.08
62.80
aggregate decode tok/s
146.5
200.29
251.13
Mia publishes one value for its high-accept prompt family without saying which prompt, so both of ours are shown.
At two streams the structured aggregate falls below Mia's published figure: the release build serializes low-concurrency work below its eight-sequence graph floor, the same artifact the internal ablation shows at three streams.
Measured on 2026-09-02 against the release build held immutable, three Sparks, warm server. FlyCockpit T0 script at commit 9093765c; Mia tests/bench_decode.py at commit c190db1a; sparkDash release 1.8.5 at commit e93fc87d.
Historical screen, two Sparks against three
Single-stream decode, tok/s
Structured count
1.41xratio
JSpark3 v1.0.0, 3 Sparks81.962
Mia TP2, 2 Sparks57.970
Code
1.49xratio
JSpark3 v1.0.0, 3 Sparks66.257
Mia TP2, 2 Sparks44.563
Prose
1.45xratio
JSpark3 v1.0.0, 3 Sparks29.049
Mia TP2, 2 Sparks20.039
Same frozen 24-request screen on the same fleet, thinking off, temperature 0, 400 max tokens. The Mia recipe is the current two-Spark release at commit c190db1a, run here with one compatibility repair.
Comparison as measured in September 2026; other projects have released newer versions since.
Historical task, same prompt
Aggregate decode, tok/s
JSpark3 v1.0.03 Sparks44.583
FlyCockpit-derived build3 Sparks29.042
Mia TP2, historical recipe2 Sparks24.913
Mia TP2, current recipe2 Sparks24.728
One agent prompt, independent runs; each agent chose its own path.
Comparison as measured in September 2026; other projects have released newer versions since.
Two Mia TP2 lineages and one FlyCockpit-derived build were run on this fleet with disclosed adaptations, and each was given the same agent prompt as JSpark3. Same prompt, independent trajectories: product evidence, not an engine-rate comparison.
JSpark3 v1.0.0
3 Sparkslocal · historical v1.0.0
44.583 tok/s aggregate decode over 132 requests and 32,618 generated tokens; mean time to first token 3.704 s.
Mia TP2, historical recipe
2 Sparkssite and safety adapted
Commit 0e2e78f, run locally with site, storage, API, and safety adaptations. 24.913 tok/s aggregate decode over 43 requests and 105,198 generated tokens.
Mia TP2, current recipe
2 Sparkscompatibility adapted
Commit c190db1a, runnable at full context only with the GLM53_INDEXER_WORKSPACE=rightsize repair: an adapted reproduction, not an exact one. 24.728 tok/s aggregate decode over 24 requests and 76,540 generated tokens.
FlyCockpit-derived build
3 Sparksminimal-correctness adapted
Commit 9093765c with minimal correctness and safety adaptations, not the literal upstream launcher. 29.042 tok/s aggregate decode over 58 requests and 130,971 generated tokens.
Comparison as measured in September 2026; other projects have released newer versions since.
These historical v1.0.0 comparisons use recipes publicly available before JSpark3. Their numbers are author-reported; ours come from our own fleet. The prompts, test tools, settings and machine counts differ, so these figures do not establish a ranking. We do not calculate percentage gains between rows.
JSpark3 v1.0.0
3 Sparks
Model and software
EXL3/TR3 4-bpw · DFlash2 k=7 · W8A16 trunk overlay · vLLM, TP3/EP3 over a RoCE-v2 triangle
Conversation limit, tokens
1,000,000
One answer, tokens/s
81.962structured count66.257code29.049prose
Test conditions
Local. Frozen 24-request screen, thinking off, temperature 0, 400 max tokens, warm server; medians of three batteries; per-stream estimator
FlyCockpit TP3
3 Sparks
Model and software
Brandon M. Music's EXL3/TR3 4-bpw checkpoint, Mia-AiLab's byte-identical re-host by default · DFlash2 k=7 · vLLM, TP3/EP3 over a mesh
Author-reported first-serve runs at commit 9093765c; thinking off, temperature 0, 200-token stops (17 for "hello"); GPU memory utilization 0.87 with cgroup swap recorded; no prose row
Mia TP2
2 Sparks
Model and software
Brandon M. Music's EXL3/TR3 4-bpw checkpoint, Mia-AiLab's byte-identical re-host by default · DFlash2 k=7 · vLLM, TP2
Conversation limit, tokens
1,000,000
One answer, tokens/s
62.9 on high-accept prompts (sparkDash, single stream) · structured 65.1 / prose 27.1 (bench_decode, four streams, median of 5×400)
Test conditions
Author-reported at commit c190db1a; two instruments of their own, neither is our screen; two Sparks, not three
jetnet TP3
3 Sparks
Model and software
NVFP4 · MTP-4 or DFlash2 · eager, Marlin W4A16, TP3
Conversation limit, tokens
512K
One answer, tokens/s
35.2 (range 32.1 to 39.0) with MTP-4 · 47.2 with DFlash2, thinking on
Test conditions
Author-reported at commits bfc820ec and 4fdba004 and the author's NVIDIA forum post; clock-capped at 1500 MHz; the model always thinks; a different quantization lane
Brandon M. Music created the EXL3/TR3 4-bpw checkpoint. Mia’s and FlyCockpit’s GLM recipes download Mia-AiLab’s byte-identical re-host by default. Mia’s recipe can also download Brandon’s source checkpoint, and both recipes can reuse files already on disk. Those defaults alone do not tell us which files a past run used. The jetnet recipe uses a different version of GLM from LibertAIDAI. Matching model files does not mean the recipes will run at the same speed.
The rows record each test’s machine count, model format, helper model, conversation length, task and source. The benchmarks page links to the exact software versions. These historical test records retain their original technical labels.
Figures as published by their authors, collected in September 2026; other projects have released newer versions since.
Internal ablation
The control is JSpark3 itself with one switch off. Same three Sparks, same pinned checkpoint and DFlash2 draft, same container image, same TP3/EP3 topology and serving envelope, same request sets and estimator. The only change is that the selective W8A16/Marlin trunk overlay is disabled, so the trunk serves in BF16 as it came from upstream. That build is unreleased internal development evidence, not a product and not a market comparison; it exists to isolate what the overlay alone changed.
Every bar below is JSpark3 measured against that control. Two single-stream rows are shown: the campaign medians against the control's earlier battery, and a strict same-day pair (candidate battery r3 against control battery r6). Green went up, red went down, one scale.
Single-stream decode · campaign medians vs the control's earlier battery
Code
+3.75%
Structured count
+5.74%
Prose
+2.62%
Single-stream decode · same-day pair, candidate r3 vs control r6
Code
+7.27%
Structured count
+6.63%
Prose
+8.35%
C6 per-stream median
+2.91%
Matched concurrency waves · aggregate service throughput
C12
+0.16%
C24
+1.21%
C48
+3.47%
Matched long prefill · 113,908 tokens
Prefill proxy
−3.38%
−5%−2.5%0%+2.5%+5%+7.5%+10%
What the overlay improved. Single-stream decode medians: code +3.75%, structured count +5.74%, prose +2.62% against the control's earlier battery; +7.27%, +6.63% and +8.35% in the strict same-day pair. Token pacing: median inter-token interval 98.645 to 91.912 ms (−6.83%), p99 −10.27%, worst interval 364.416 to 148.344 ms (−59.29%). Aggregate throughput at 48 streams +3.47%. 1,595,392,320 bytes of weight memory freed per rank.
What it cost, and what was missed. Long prefill −3.38% with time to first token +3.50% on 113,908 tokens. Fairness did not improve. Time to first token at 48 streams reached a p90 of 96.722 s. Two internal promotion gates were missed: a code median of 66.257 against a 67.0 floor, and a demonstration pacing run of 14 against a limit below 5.
Engineering evidence from one project-operated fleet, without third-party reproduction. Cadence's paired code gain did not replicate; its quality battery has candidate-only failures. Semantic parity, sustained concurrency and maximum context remain uncertified. The repository publishes the failed sham, confidence intervals, receipts and limitations.
Run v1.1Get the setup software and model files+
Start with the v1.1.0 installation guide. It walks you through downloading the software and model files, preparing them for three Sparks, connecting the machines, and checking that the server works.
The startup scripts check that your files and settings match the tested setup. Matching them does not guarantee the same speed on your machines. You can preview each command before running it, and commands that need confirmation require you to type it. The server will not start if these checks fail:
Inputs
The GLM model, DFlash2 helper model, Docker package or source code differs from the required version.
Environment
The container must have a 64 GiB memory limit and no disk-backed swap memory. The scripts reject overrides of NCCL_PROTO, NCCL_ALGO, or NCCL_IB_ADDR_RANGE and reject changes to the required software settings.
Identity
Each Spark must pass the setup checks and have a matching record of its Docker package. Startup also stops if a container with this release’s name already exists.
Bytes
Each Spark checks that the required software changes are applied once, in the right places, and that the resulting files match the expected contents.
Download versionsModel and software versions+
The setup uses fixed versions of the model and software. It checks the files before starting the server. The version links and file identifiers below let you verify your downloads.
incoai/GLM-5.3-Flash-DFlash2 at revision dc77ff1c99eeb2df044ee3d4f0094eb033fee410. This smaller model helps generate answers faster. It usually suggests seven tokens (pieces of text) at a time. Cadence can use three when answering one request.
Docker software package
ghcr.io/miaai-lab/glm-5.3-flash-2x-dgx-sparks with this exact file identifier: sha256:9bb1557a4234fce63d59599e44d10747eabd742beb337eebf9e7070be8a0fd58. Download this package from Mia’s registry; JSPARK3 does not distribute a copy.
Serving engine
vLLM build 487ecf187 runs the model and answers requests. It comes with the Docker package above. At startup, the scripts apply the required software changes and verify each changed file.
Sources for software changes
FlyCockpit GLM-5.3-Flash-EXL3-3x-DGX-Sparks at 9093765c757bd1976372196e44af84a67cf86bad; vcruz305 GLM-5.3-Flash-EXL3-K2-DGX-Spark-recipe at 622cb878d66f703c597bd6baaa2423caa1786f99
Server settings
The settings allow up to 1,000,000 tokens of conversation and 32 requests at once; those limits are not certified capacity. Each processing step handles up to 8,192 tokens. The GPU memory setting is 0.83. It saves some working data in an 8-bit format (FP8) and can reuse calculations when prompts begin with the same text. The API model name is glm-5.3-flash
LicensingThree licenses, plainly+
The recipe is ours to license. The model bytes it loads are not. Read this before deploying for anything commercial.
Recipe code
Apache-2.0
The scripts, overlays, transforms, tooling, and documentation, with third-party notices. Use, modify, redistribute.
Target checkpoint
ShapleyMcg License 1.0
Source-available and attribution-required, with a named exclusion; not OSI open source. Brandon M. Music created the EXL3/TR3 checkpoint. Mia-AiLab and JSpark3 re-host it under the same terms, with verbatim attribution. Downstream copies stay under this license.
DFlash2 draft
CC BY-NC-ND 4.0
Research and evaluation only. Commercial use of the draft requires permission from Inco AI. The pinned serving recipe includes this separately downloaded draft.
The assembled endpoint is therefore neither unrestricted open source nor commercial-ready. The repository's licensing page lists every term and its practical effect, and the ownership statements the project does not make.
I had three DGX Sparks and wanted one model server. JSpark3 makes three work: GLM-5.3 Flash across all of them as one OpenAI-compatible endpoint. Version 1.1, Cadence, adds measured single-stream decode improvements and the long-context kernel fix. The recipe is pinned so you can rebuild it, with public benchmarks and the misses left in.
68.77 tok/s
single-stream code decode, v1.1: descriptive median of three battery medians
87.67 tok/s
structured decode, v1.1: code 68.77, prose 34.64 tok/s on the same battery basis
223.14 tok/s
four-stream aggregate, v1.1: median of three original-client waves; 56.59 per stream
1,234 tok/s
historical v1.0.0 prefill on 113,908 tokens; no comparable v1.1 measurement